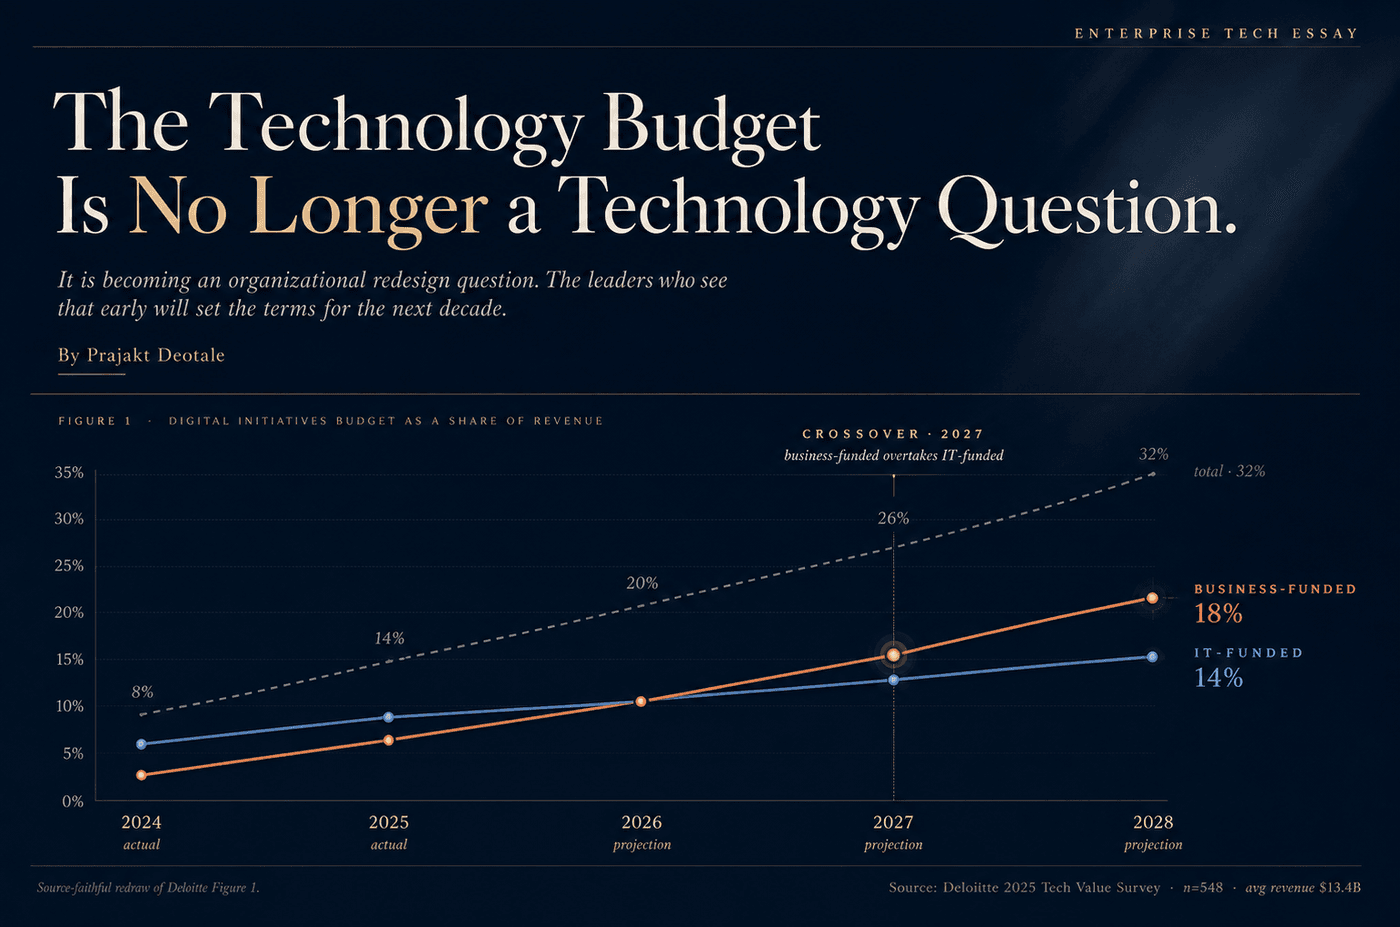
By 2027 the business-funded technology budget overtakes the IT-funded one. That is not a budgeting story. It is an organisational redesign story.
It is becoming an organisational redesign question, and the leaders who see that early will set the terms for the next decade.
Figure 1. Digital initiatives budget as a share of revenue. The business-funded line overtakes the IT-funded line in 2027, with total digital spend on a path to roughly 32% of revenue by 2028.
Over the past year I have found myself in many conversations that begin in a familiar way: a CEO, CFO, CIO or Chief AI Officer, an AI roadmap, and a technology budget being defended as a technology budget.
I think that framing is now the wrong one. AI is obviously technology. But the spending pattern building underneath these conversations has stopped behaving like technology spend. This essay is about why I think the line has moved.
The chart that changed how I read this
Most years, the enterprise tech spending data is a slow drift. Cloud takes a few points from on-premises. SaaS pulls a few points from licensed software.
The 2025 Deloitte data does not look like that. The digital initiatives budget moved from about 8% of revenue in 2024 to about 14% in 2025 in a single year. But it is not the headline that matters. The headline that matters sits underneath.
Deloitte tracks the budget in two pieces: the IT-funded portion and the business-funded portion. In 2024, IT-funded spend was the larger of the two by a wide margin. By 2025, the gap had narrowed sharply. By 2026, on Deloitte’s projection, the two lines meet. By 2027, the business-funded line overtakes the IT-funded line for the first time.
That is the chart that changed how I read this.
What it tells me is that the technology budget is not just doubling. The boundary of who controls the bigger half is moving outside the technology function. For the better part of two decades, shadow IT was the name we gave to the pieces of the technology estate that drifted into the business. We treated it as a governance problem. The 2027 crossover suggests it was never the problem. It was the early signal of a structural shift the data is now confirming at scale.
Why the lines diverge, and why the IT line still rises
When I show this chart to operators, the first question is always the same. If AI is supposed to recentralise spend into IT, why is the non-IT line growing faster?
The mechanism is actually simple, and once you see it the chart explains itself.
The IT-funded line keeps rising because AI’s foundations have nowhere else to live. Data architecture, model governance, identity and access, inference infrastructure, and the cyber posture required to deploy any of this safely. None of that fits inside a marketing budget or an HR budget. The technology function has to scale to carry the weight of what gets built on top of it. Deloitte is direct about this in their own commentary: AI risks starving the rest of the technology portfolio if digital budgets do not continue to expand. The IT line is rising because the foundation is being asked to do more.
The business-funded line rises faster because the use cases land outside IT. Customer service is buying AI for handle time. Marketing is buying it for personalisation. Legal is buying it for review and contract drafting. Finance is buying it for close acceleration. HR is buying it for sourcing and screening. None of these functions are routing through IT to procure the tools. They are sizing the budget themselves, configuring against their own data, and absorbing the cost line into their own profit and loss.
Figure 2. The two funding lines. IT-funded and business-funded technology spend, and where they cross.
Both things are happening. Both lines rise. The non-IT line rises faster because that is where the application layer of AI is being absorbed. The IT line rises because it has to. The result is a structurally larger technology estate where the bigger half is no longer governed by the technology function.
That is not a budgeting story. That is an organisational design story.
What is actually being purchased
The other thing I keep coming back to is what enterprises are actually buying when they buy AI.
Sequoia put a useful frame on this in their Services: The New Software analysis earlier this year. For every dollar spent globally on software, roughly six dollars are spent on services, the labour that gets work done. Software, in aggregate market terms, has always been a small slice of the total cost of completing enterprise work. Services and labour have been the rest.
The AI products winning at scale right now are not selling better tools for human workers. They are selling the work itself. They compete inside the labour pool, not the software pool. That is a completely different market and a completely different price ceiling.
This is the part I think most enterprise tech budgeting still misses. If you measure the AI opportunity as software spend, the curve looks stretched. If you measure it as the cost of completing the work, it has barely started. The 32% of revenue Deloitte projects by 2028 only looks aggressive against a software anchor. Against a services and labour anchor, 32% is the early phase, not the late one.
Figure 3. Software against services. For every dollar spent on software, roughly six are spent on the labour that gets the work done.
Which is why the budget conversation and the organisational conversation are now the same conversation.
Where the labour pressure shows up first
If AI is competing for services and labour budgets, and the data increasingly says it is, then the next question is not financial. It is structural. What happens to the labour those budgets used to fund?
I want to be careful here. The temptation is to make AI carry the weight of every workforce headline currently in the news. It cannot, and it should not. Many of the layoffs visible in the technology sector right now are also responses to overhiring during 2020 to 2022, post-ZIRP cost discipline, and rising compute costs eating into margin. AI is one force among several. The honest read is to say so.
What I do think is worth saying, because it is grounded in the historical record rather than in current headlines, is this. Major general-purpose technology transitions tend to produce labour pressure first in the sectors closest to adoption.
The Industrial Revolution did not begin restructuring labour across the broad economy. It began restructuring labour inside textiles, the industry adopting the new spinning and weaving technologies first. The Luddite movement of 1811 to 1816 was a textile-worker phenomenon, not a general workforce one. The pressure propagated outward to broader manufacturing only as the technology matured.
Electrification followed a similar pattern. The early organisational impact was felt inside manufacturing, where electric motors eventually changed factory layout, workflow, and the relationship between power and production. The wider economy felt it later.
The personal computing wave first put sustained pressure on routine clerical and administrative work, the kind of codifiable office activity that software could gradually absorb. The internet transition compressed dramatically inside travel agencies, classified-ad businesses, and directly disintermediated retail before the broader economy felt it.
The pattern is consistent. Labour pressure first appears inside the industry closest to the technology, then propagates outward as the technology matures.
What is distinctive about this transition, and this is the observation I have not been able to find a precedent for, is that the technology builders themselves are showing labour pressure during the build-out phase, not after diffusion. In every prior transition, the builders of the technology hired aggressively while the directly displaced industries shrank. The two groups were distinct. In this transition, they sit much closer together, because AI’s first competent applications happen to be concentrated in tasks performed inside technology firms themselves: code, support, content, recruiting.
I do not think this means the historical pattern is broken. I think it means the historical pattern is compressing. The propagation that took decades in prior transitions may take years in this one. The forward-looking implication is open-ended on purpose, because the pace and sequence of propagation are genuinely uncertain. But the direction is not.
The optimistic frame is the one that has held up across every prior transition. Each one expanded the economic pie. Each one created entirely new categories of work. Each one rewarded the workers and firms that adapted earliest with most of the upside. The current phase is the transition, not the destination. The leaders who treat it as a cost-takeout exercise will solve the wrong problem. The ones who treat it as an organisational redesign will set the terms for what comes next.
That is the specific work I think the next eighteen months are about.
What the redesign actually looks like
I work mostly with telecom operators, and telecom is a useful case study right now precisely because it has stopped being theoretical. The most AI-fluent industry has begun repositioning, and what that repositioning looks like is becoming visible in the operating data.
McKinsey’s recent telco analysis finds 57% of telco executives report scaling generative AI use cases across multiple domains. The same survey shows the share of executives describing AI as a blockbuster technology actually declined, from 61% in the prior round to 51% now. The most AI-fluent industry is becoming less breathless about AI even as it deploys it more aggressively. That combination, falling rhetoric and rising deployment, is what industrial maturation looks like. And McKinsey projects AI could deliver 8 to 10 EBITDA percentage points to telco operators over five years. A structural margin uplift of that size is historically rare for a mature industry.
Figure 4. Telecom as the leading indicator. Scaled deployment rising while the rhetoric cools, with a projected 8 to 10 point EBITDA contribution over five years.
The clearest production data point in the public record right now is AT&T’s deployment with Microsoft Azure. More than seventy unique generative AI solutions in production. Nine billion daily tokens of measured deployment volume. More than a hundred thousand employees using generative AI tools. Thirty-three percent faster agent productivity in customer-service interactions. Year-on-year return improvement reported by the deployment team.
What that case shows is not that AT&T has an AI strategy. Plenty of companies have AI strategies. What it shows is what an AI-fluent industry’s production deployment template looks like at scale. Solutions in production. Six-figure employee adoption. Billions of tokens in measured volume. An EBITDA path. The template is portable. Other industries with comparable cost structures and customer bases can read AT&T’s deployment as an operational reference, not an aspirational one.
The reason telecom matters here is not that it predicts what every industry will do next. It is that it shows what the redesign looks like once it stops being a technology project and becomes an operating model. That distinction is the entire point of this essay.
The bubble question, briefly
I should address the framing question that keeps appearing in this debate, because it is a fair one. Is this a bubble?
A classical bubble shows demand weakening while supply catches up. Valuations compress before fundamentals do. The 2025 to 2026 data does not look like that pattern. Budgets are expanding, not contracting. The supply side is still racing to catch up. Production deployments are scaling, not stalling. Operational metrics are improving where they are being measured.
This is interpretation, not proof. Plenty of individual AI investments will fail to produce returns. The MIT NANDA work that Deloitte itself cites finds only about 5% of generative AI pilots deliver sustained value at scale, and that gap is real. The aggregate spending curve being structurally sound does not mean every dollar within it will be well spent.
The risk I think is more concrete than the bubble framing is measurement mismatch, where leaders size AI as a software line item when it is structurally a services phenomenon, and foundation starvation, where AI dollars go into models while the data, security, and identity infrastructure those models require to deploy safely stays underfunded. Deloitte’s own report flags this directly. Only 25% to 32% of organisations invested in identity management, federated security, or zero trust in the past year, even as AI deployment accelerated. That gap is the more immediate strategic risk in the data than any aggregate-curve bubble.
What I would ask
If I were writing this for the leadership team I worked with most recently, I would close on the questions I think now matter more than the budget.
When 25 to 30% of revenue is being deployed against work rather than against software, what does the organisation actually look like? Which functions stop being functions and become flywheels? Which centralised capabilities, meaning data, governance, security and infrastructure, have to be funded as foundational rather than as project costs? Where does the labour redesign live in the org chart, and who owns it?
These are not budgeting questions. They are design questions. And they are the right questions, because the technology budget is no longer a technology question.
The leaders asking them in 2026 will own the next decade. The leaders still arguing about the IT line will be answering them in 2030, by then on someone else’s terms.
The opportunity here is not to manage the curve. It is to design what comes out the other side.
Sources
Deloitte Center for Integrated Research, AI and tech investment ROI, 2025 Tech Value Survey, October 2025. n=548, average revenue $13.4B. Digital initiatives budget 7.5% in 2024 to 13.7% in 2025, with a continuation projection to roughly 32% by 2028, the IT-funded and business-funded split with crossover by 2027, 74% AI investor share, 36% average AI share of digital budget, cybersecurity investment gap of 25% to 32%, and the MIT NANDA 5% pilot success citation.
Sequoia Capital, Services: The New Software, 2026. The $1 to $6 software-to-services ratio.
McKinsey & Company, The AI Inflection Point: What Leaders Do to Capture Value, telco industry analysis. 57% scaling generative AI across domains, 51% against 61% on framing, and the 8 to 10 percentage point EBITDA five-year projection.
Microsoft customer story and AT&T deployment with Microsoft Azure: more than 70 unique generative AI solutions in production, 9 billion tokens, more than 100,000 employees, and 33% faster agent productivity in customer-service interactions.
This essay was first published on the Brain AI Insights page on 15 June 2026.
A framework that integrates capex, revenue conversion, physical bottlenecks and demand elasticity, and introduces two metrics that do not appear in published analysis.
A working paper from Brain AI. Prajakt Deotale, May 2026.
Executive summary
The AI build is the largest concentrated infrastructure cycle in technology history. The four largest hyperscalers will commit close to seven hundred billion dollars in 2026 alone. Capex commitments are tracking toward a trillion dollars in 2027. And yet the market cannot agree on what to make of it. The world’s most influential capital allocators are publicly disagreeing about whether this is a once-in-a-century opportunity or the start of a correction.
The disagreement is not noise. It is a sign that the analytical frameworks used to read AI compute economics have run out of vocabulary. Each camp picks the variables that suit its narrative and reaches the conclusion that suits the variables. None of the existing analyses integrates the moving parts: capex, revenue conversion, physical bottlenecks, demand elasticity, geopolitical concentration. Each matters, and each has been tracked in isolation. The interactions between them are where the action is, and where commentary is currently silent.
This paper offers a framework that integrates the moving parts. It introduces two metrics that fill the most obvious gaps in published analysis. The first asks how much of the announced capex actually becomes deployed compute on the schedule the market is pricing. Today the answer is roughly fifty five percent. The second asks where the money goes when unit costs fall. The answer is striking: roughly seventeen times more demand is being pulled into the system than would be expected from the cost decline alone, and that ratio is rising, not falling.
The strategic implication is that the bubble debate is the wrong debate. The real question is which transition the system unfolds into next, and on what timeline. This paper offers seven dimensions of structural pressure to watch, two ratios that condense them, and four years of post-ChatGPT data to anchor the reading. The framework will not predict the future. It gives executives a structured way to see where the system is, and to recognise the leading indicators of where it could go.
1. The wrong question
On April 29, 2026, the four largest hyperscalers reported earnings on the same evening. By the close of the next trading day, their stock reactions told four different stories. Alphabet rallied on a five billion dollar capex hike. Meta fell six percent on a ten billion dollar capex hike. Microsoft slid two and a half percent. Amazon traded sideways. The combined 2026 capex commitment from these four companies now stands at roughly seven hundred billion dollars, the largest concentrated infrastructure cycle in technology history. And yet the market cannot agree on what to make of it.
In the week that followed, two of the most influential voices in capital markets weighed in. Larry Fink told the Milken Institute conference on May 5 that the AI build is a supply crunch rather than a bubble, and called it a once-in-a-century investment opportunity that will require ten trillion dollars of US capex over the next decade or more. Jamie Dimon, speaking the next day at an event in New York, said the trillion dollar data centre cycle will make sense in aggregate, while adding that technology tends to pay for itself but not in a straight line, and that picking individual winners and losers within the cycle would be hard. Two extraordinary statements from two of the world’s most powerful capital allocators, on consecutive days. Both rejected the bubble framing. Neither offered the analytical infrastructure their position implies.
The market fragmentation around these positions is not noise. It is an honest acknowledgment that the existing analytical frameworks have run out of vocabulary. Capex to revenue ratios tell one story. Backlog conversion tells another. Physical bottlenecks tell a third. Credit market concentration tells a fourth. Each camp is right about its own variable. None is right about the system as a whole.
This paper offers a different way to read AI compute economics. It treats the system as a transition story across multiple structural forces, and shows how the interaction of those forces produces the conditions investors are now pricing differently for different companies. It introduces two metrics that do not appear in any published analysis we could find. The Capex Translation Rate measures how much announced capex actually becomes deployed compute. The Efficiency Absorption Ratio measures how falling unit costs are converting into demand expansion. Together they explain why the same numbers can support such different interpretations.
The framework does not predict where the AI compute economy is going. It gives executives a structured way to read where it is, and to recognise the leading indicators of where it could go next. With capex commitments tracking toward a trillion dollars in 2027, the cost of reading the system wrong has become structural rather than tactical.
2. The five conditions
The framework treats AI compute economics as a system that moves between distinct states, much as macroeconomies move between expansion, recession and recovery. Five conditions capture the full range of states the system can occupy. They are not a sequence; the system can move between them in either direction.
Scarcity with Monetization. Demand is rising rapidly. Supply has not yet caught up. Capex is rising but the build cycle has not fully responded. Bottlenecks are emerging but not yet binding. Investors are constructive. This was the AI compute economy through most of 2023.
Catch-up Buildout. Demand remains strong. Capex has accelerated to match or exceed demand growth. Physical bottlenecks are now binding the rate at which capex translates into deployable supply. Investors are watching closely but not punishing. This has been the dominant condition through 2024 and 2025.
Catch-up Buildout with Vapor Capex. Same as Catch-up Buildout, with one critical addition: announced capex is materially overstating the compute that will actually deploy on schedule. The gap between announcement and deployment becomes a structural feature.
Balanced Expansion. Demand and supply grow in line. Bottlenecks are managed. Adoption broadens beyond frontier model providers and into enterprise production. This is the condition the industry is trying to walk into. It has not been observed yet.
Speculative Overshoot. Demand softens or becomes concentrated in a few customers. Capex continues to rise because the build cycle has not yet pulled back. Bottlenecks ease as supply catches up to weakening demand. Investors begin punishing capex. Algorithmic efficiency stops pulling new demand into the system. This is the condition the bubble framing assumes is already underway. The framework does not see evidence of it today.
Correction and Digestion. Capex pulls back sharply. Excess capacity gets absorbed over multiple years. AI revenue continues to grow but the investment cycle becomes more disciplined. Speculative Overshoot leads here.
Figure 1. The five conditions of AI compute economics.
Each condition is defined relationally, by the relationship between dimensions, not by absolute thresholds. Scarcity is the condition where demand races ahead of supply response. Catch-up is the condition where buildout has caught up and is racing to scale. Overshoot is the condition where buildout continues while demand softens. The relational definition matters because the system can occupy the same condition at very different absolute scales.
A companion scorecard, published alongside this paper, classifies every quarter from late 2022 to early 2026 against these conditions, using seven structural dimensions and explicit rules.
3. Where we have been since November 2022
ChatGPT launched on November 30, 2022. From that moment to today, the AI compute economy has walked through four distinct conditions.
For most of 2023, the system was in Scarcity with Monetization. NVIDIA’s data centre revenue went from 3.6 billion dollars in the fourth quarter of fiscal 2023 to 14.5 billion dollars just three quarters later. Hyperscaler capex was rising but had not yet fully responded. Microsoft extended its OpenAI partnership in January. Amazon committed to Anthropic in September. Demand was racing ahead of the supply response.
The transition to Catch-up Buildout happened in early 2024. Hyperscaler capex caught up to demand and then began to outpace it. Aggregate hyperscaler capex for 2024 came in around 240 billion dollars, a step change from the prior baseline. Memory costs began to climb, transformer lead times began to extend, and the physical bottlenecks that had been latent in the Scarcity period started to bind.
Through 2024 and into 2025, Catch-up Buildout deepened. Aggregate hyperscaler capex reached 400 to 450 billion dollars. NVIDIA’s data centre revenue ran past 35 billion dollars per quarter. OpenAI hit a one billion dollar monthly run rate. Anthropic crossed seven billion dollars in annualised revenue mid-year, ended 2025 at roughly nine billion, and disclosed at its developer conference this week that the run rate had reached thirty billion in the first quarter of 2026. The build cycle was racing the demand cycle at scales the industry had never operated at before.
The shift to Catch-up Buildout with Vapor Capex came in mid 2025. Sightline Climate’s pipeline tracking made clear that the volume of announced data centre capacity was running well ahead of the volume actually under construction. Memory contract prices spiked. SK Hynix declared its forward production sold out for 2026. The Capex Translation Rate dropped through 65 percent, the threshold at which announced capex begins to materially overstate near term deployable compute.
Figure 2. The condition path since November 2022.
By the fourth quarter of 2025, a new pattern emerged. Investor pressure began to differentiate between hyperscalers. Capex announcements that would have been uniformly rewarded in 2024 now produced opposite reactions. Goldman Sachs reported that the correlation among hyperscaler stocks had fallen from around eighty percent at the start of the cycle to around twenty percent by year end. The system entered what the framework calls D-risk, the leading edge of delayed overshoot risk, while still primarily in Catch-up Buildout with Vapor Capex active. That is where today sits.
4. The two physical walls
The standard analyst chain runs as follows. Hyperscalers announce capex. Eighteen months later that capex becomes deployed compute. Compute serves demand. Demand generates revenue. The chain assumes capex translates one to one into deployed supply.
The chain is no longer accurate. Two physical walls now sit between announcement and deployment, and both are getting worse.
The first is the memory wall. Inference workloads are increasingly bound by memory bandwidth rather than by raw computation. The latency of an inference call cannot fall below the slower of two pipes feeding the GPU: the compute pipe or the memory pipe. For long context, agentic and reasoning workloads, the memory pipe dominates. High Bandwidth Memory has therefore become the actual scarcity. SK Hynix, Samsung and Micron supply almost the entire global market. Forward commitments from hyperscalers now extend three years, meaning every HBM stack through 2028 is already spoken for. Memory’s share of hyperscaler data centre spending has risen from roughly seven percent in 2023 to around thirty percent in 2026. Microsoft attributed roughly twenty five billion dollars of its 2026 capex to higher component pricing, with memory the dominant driver. Meta’s most recent capex hike was driven almost entirely by memory.
The second is the power and grid wall. Sightline Climate’s early 2026 analysis showed that of sixteen gigawatts of US data centre capacity announced for completion in 2026, only about five gigawatts was actually under construction. Their projection was that thirty to fifty percent of the announced 2026 pipeline would slip past year end. The bottleneck is not money. It is high voltage transformers, with lead times of one hundred and forty four weeks, and grid interconnection queues that clear at perhaps one fifth of the rate that announced capacity would imply. Capital can buy a chip in months. Capital cannot manufacture a transformer.
Figure 3. The two physical walls between announcement and deployment.
This is where the framework departs from the standard bubble math. When a Cahn-style or Goldman-style analysis takes announced capex, divides it by AI revenue and produces a ratio, the implicit assumption is that announced capex equals deployed compute. The two physical walls make that assumption wrong by a wide margin.
The supply chain workarounds are also revealing. This week, Anthropic disclosed it had secured three hundred megawatts of new compute capacity at the Colossus One data centre, a procurement arrangement that would have been unusual a year ago. When even the largest hyperscalers cannot meet your forward demand, you reach outside the conventional cloud channel. That is the supply crunch made visible at the procurement level.
Sidebar: why memory dominates inference latency. An inference call performs two operations in tight loops: matrix multiplications using the GPU’s compute units, and reads of model weights and key-value cache from memory. The total latency cannot fall below the slower of these two operations. Formally, the time per token is bounded below by the maximum of compute time and memory access time. For long context windows and reasoning models, the key-value cache grows proportionally with sequence length and reasoning steps. At one million tokens of context, the cache consumes seventy to ninety percent of GPU memory and the memory pipe becomes saturated. Adding more compute does not help. Only faster or larger memory does.
5. The Capex Translation Rate
If announced capex no longer equals deployed compute, then any analysis comparing announced capex to revenue is comparing the wrong number to the right one. The Capex Translation Rate is the framework’s response to that gap.
CTR measures the fraction of announced capex that converts into deployed, energised, revenue-generating compute within eighteen months. The eighteen month window is the standard build cycle assumed by analysts. Anything that arrives later is either deferred or phantom.
Today’s CTR sits at roughly fifty five percent. The number is anchored to Sightline Climate’s pipeline data. Of sixteen gigawatts announced for 2026, the midpoint of expected slippage implies that around sixty percent will reach commercial operation on schedule. We adjust modestly downward to account for the gap between coming online and being fully revenue generating.
Three implications follow.
First, the bubble debate is being held against the wrong denominator. When announced capex is compared to disclosed AI revenue, the gap looks alarming because the numerator overstates near term reality by something close to a factor of two. A more honest comparison would look at deployed compute against revenue, and the picture would be considerably less dramatic.
Figure 6. The bubble math depends on which numerator you pick. Narrow measure, disclosed OpenAI and Anthropic ARR against 2025 hyperscaler capex: 6.8 percent. Broader measure including full AI revenue across cloud and productivity products: 58.8 percent. An 8.6x difference. Both are correct; they measure different things.
Second, today’s apparent Catch-up Buildout is partly masked. The framework’s CTR threshold of sixty five percent triggers the Vapor Capex condition. Today’s reading of fifty five percent puts us inside that condition. Roughly forty five percent of announced capacity is at risk of arriving late or not at all on the schedule the market is currently pricing.
Third, the Vapor Capex condition creates a delayed overshoot risk. If the bottlenecks eventually clear, and they will, the deferred capacity arrives in waves. If demand has softened by then, the delayed wave arrives into a market that no longer needs it. That is the mechanism by which today’s bottlenecks could mask tomorrow’s overshoot. It is a transition risk the standard frameworks do not see, because they are not measuring the gap.
When Jamie Dimon said this week that the trillion dollar data centre cycle will make sense but that technology tends to pay for itself and not in a straight line, he was describing in plain English what CTR measures formally. A straight line implies announced capex equalling deployed compute on the analyst timeline. The line is not straight. CTR puts a number on how curved it has become.
6. Reasoning models and the memory wall
A natural response is to expect that algorithmic efficiency will save us. Inference costs have fallen by roughly an order of magnitude per year since 2023. By the cleanest benchmark, GPT-4 quality inference cost has fallen by a factor of around sixty in eighteen months. Surely the falling unit cost relieves the pressure on physical infrastructure?
The data says the opposite.
When unit costs fell tenfold over the past year, token volumes rose by considerably more. Google reported processing roughly one hundred times more tokens per month at the middle of 2025 than a year earlier. OpenAI’s compute capacity grew from 0.2 gigawatts to 1.9 gigawatts between 2023 and 2025, a tenfold increase, while inference costs were collapsing. Enterprise generative AI spending grew roughly three hundred and twenty percent in 2025 even as per token costs fell by a factor of one thousand against the GPT-3 baseline.
This is Jevons paradox in real time. Falling unit costs are not relieving infrastructure pressure. They are intensifying it, by making AI feasible for use cases that were previously priced out. Each new use case adds tokens. Each token costs less but the total bill keeps rising.
This is also the supply side of the same story, articulated by the operator most affected by it. At Anthropic’s developer conference this week, Dario Amodei disclosed that the company’s revenue and usage had grown roughly eighty fold year over year in the first quarter of 2026, against an internal plan that had assumed tenfold growth, and said that this was the reason the company had experienced difficulties with compute. The most aggressive demand forecast inside one of the world’s two leading AI labs was wrong by a factor of eight, on the upside, and the binding constraint was supply. Jevons paradox is no longer an analytical curiosity. It is the planning reality at the centre of the cycle.
Reasoning models make this worse. A reasoning model generates thousands of internal tokens before producing a final answer. Where ChatGPT used to respond to a one sentence question with a one sentence reply, a reasoning model now spends three minutes planning, twenty minutes searching, and five minutes writing. The output may be much better. Token consumption per task has risen by factors of fifty or more.
The interaction with the memory wall is the unobvious part. Reasoning workloads are memory bandwidth bound. The longer the reasoning trace, the larger the key-value cache, the more memory bandwidth each inference call requires. Algorithmic improvements that have driven cost reductions over the last two years have not relieved the memory wall. They have made it more binding. The frontier of AI is moving toward workloads that are precisely the workloads HBM was built for, at exactly the moment that HBM is the most constrained input in the entire stack.
Most AI economics work treats algorithmic efficiency as a tailwind that gets out of the way of the physical buildout. The data suggests the opposite. Efficiency is a demand multiplier that intensifies the physical buildout. It does not relieve scarcity. It deepens it.
7. The Efficiency Absorption Ratio
The Efficiency Absorption Ratio is the framework’s response to that observation. It measures how much of the unit cost decline is being absorbed by demand expansion versus how much is being converted into cost savings.
The calculation is straightforward. Take the cost decline multiplier, expressed as how many times cheaper inference has become against a 2023 base. Take the volume expansion multiplier, expressed as how many times more inference is happening than in 2023. Divide volume by cost. The result is EAR.
By 2024, against a 2023 base, inference unit costs had fallen by roughly a factor of three while volume had risen by a factor of eight. EAR was approximately 2.7x. By 2025, costs were ten times cheaper and volumes were sixty times larger. EAR was approximately 6x. Today, costs are roughly thirty times cheaper than the 2023 baseline and volumes are roughly five hundred times larger. EAR is approximately 17x.
Figure 4. The two ratios that change the debate. CTR at 55 percent, EAR at 17x, first quarter 2026.
The number is striking, but the trajectory is the real story. EAR is rising, not falling. Each successive year, falling unit costs pull more incremental demand into the system than the year before. Demand expansion is not just keeping pace with efficiency gains. It is accelerating ahead of them.
The strategic implication is the most important point in the paper. The fibre glut of 2001 had no equivalent of EAR. When fibre supply ran ahead of demand, the price of bandwidth collapsed and demand did not absorb the excess for nearly a decade. The capacity sat idle. AI is not in that situation. If supply briefly runs ahead of demand, falling unit costs will pull additional demand into the system. The demand elasticity mechanism is structural and is functioning in real time.
This does not mean overshoot is impossible. It means overshoot would require EAR to break. A drop in EAR below 1x, which would mean falling unit costs were starting to convert into cost savings rather than demand expansion, would be the leading signal of a true regime transition. We have no evidence of that today.
CTR and EAR together change the bubble debate by replacing the wrong question with the right ones. CTR asks how much announced capex actually arrives. EAR asks where the money goes when costs fall. Together they produce a more honest picture than the analyses currently in market.
8. Five paths to 2030
The framework does not predict the future. It gives executives a structured way to read where the system is and what would have to be true for it to move in particular directions.
Figure 5. Five paths to 2030, from today’s Catch-up Buildout with Vapor Capex.
Balanced Expansion would require the bottlenecks to ease in step with demand growth. CTR rises from today’s fifty five percent toward eighty percent by 2030 as memory capacity expands and transformer lead times normalise. AI revenue grows at thirty to forty percent annually, capex at fifteen to twenty percent. EAR settles into a healthy band of one to three times.
Extended Scarcity would require bottlenecks to persist. CTR stays in the fifty to sixty percent range through 2030. Demand keeps rising but supply cannot catch up. Pricing power is retained. EAR stays above five times.
Speculative Overshoot is the path the market is watching for. Bottlenecks clear faster than expected, perhaps because Samsung’s Pyeongtaek memory capacity comes online in 2028 and transformer manufacturing scales by 2029. The deferred capacity from today’s Vapor Capex condition arrives in a wave. Simultaneously, AI revenue growth slows or concentrates. EAR drops below one. At least one major hyperscaler announces a capex cut or write down. AI exposed equities reset.
Correction and Digestion is the same trigger as Speculative Overshoot but with a longer absorption period. Capex pulls back. Excess capacity gets absorbed over two or three years. AI revenue continues to grow at perhaps twenty to twenty five percent because demand never collapsed. The narrative shifts from more compute to more efficient compute.
Productivity Breakout is the most optimistic path. Reasoning and agentic AI drive a step change in enterprise demand starting in 2027. Inference costs continue falling but volumes rise faster. EAR stays above ten times. Memory becomes the binding global constraint. AI revenue grows at fifty percent or more for two to three years.
The geopolitical dimension cuts across all five paths. HBM is concentrated in Korea. Advanced packaging is concentrated in Taiwan. Transformer manufacturing is concentrated in a handful of US, European and Asian suppliers. In stressed scenarios, geopolitical concentration binds first. The new Samsung capacity at Pyeongtaek does not reach mass production until 2028.
We do not assign probabilities to these paths. With about fourteen quarters of post-ChatGPT data and at most one observed condition transition, probability assignments would be false precision. The honest framing is that here are five plausible paths, and here are the leading indicators that signal which one is unfolding. Watch CTR. Watch EAR. Watch the seven dimensions. The system will tell you which path is materialising long before any commentator does.
9. What this means for enterprise leaders
The framework supports three kinds of decisions.
The first is investment timing. If a leadership team is committing to multi-year AI infrastructure spend, the framework offers a way to read whether the system is in a condition that supports the commitment or whether deferring would be more disciplined. Today’s reading suggests neither aggressive commitment nor full retreat. It suggests committing in stages, with explicit gates tied to the leading indicators.
The second is supplier strategy. The memory wall and the power wall will be binding for at least the next several years. Procurement strategies built on the assumption that compute and memory are commodities to be sourced opportunistically will struggle. Strategies built on multi-year supplier relationships, with explicit allocation guarantees, will hold up. The same applies to power and grid: enterprises with material AI infrastructure plans should be developing onsite generation strategies and grid interconnection optionality now.
The third is portfolio resilience, and this is where the framework speaks most directly to the moment. Most enterprises do not feel the memory wall or the power wall directly. They buy compute from a hyperscaler or AI provider, and the upstream bottleneck is hidden inside that relationship. But the bottleneck still reaches the enterprise as a second-order effect. It shows up as capacity availability for new workloads. It shows up as price changes. It shows up as which providers are able to deliver new capability quickly and which are stuck in queues. Larry Fink described what is unfolding as a K-shaped economy. Jamie Dimon, in the same week, warned that picking individual winners and losers within the AI cycle would be hard. Both observations are accurate. The framework explains why. The K-shape will play out across the providers your enterprise depends on, not across your own infrastructure decisions.
The implication is that counterparty assessment matters more than commitment scale. Some hyperscalers and AI providers will manage the upstream bottleneck better than others. Some will have secured forward HBM allocations, locked in transformer lead times, and built differentiated procurement strategies. Others will not. Anthropic’s experience this quarter is the K-shape rendered concretely: eighty fold demand growth absorbed by a procurement strategy reaching outside conventional cloud channels. The companies that built supplier relationships years ago are scaling. The companies that did not are stalled. For an enterprise, the question is not how to secure forward HBM yourself. It is how to read which side of the K your providers are on. The framework’s adoption maturity dimension and the underlying signal ledger give enterprises a structured way to assess these questions rather than relying on capex headlines.
The single most important implication is that the bubble debate, as it was framed in the financial press through 2024 and 2025, is the wrong debate to be participating in. It assumes a binary outcome when the actual question is which condition the system transitions into next. Enterprise leaders who position for a binary outcome will be wrong regardless of which side they pick.
10. Closing
Today the AI compute economy is in Catch-up Buildout with Vapor Capex active and delayed overshoot risk emerging. That is the framework’s call as of May 2026. It is anchored in seven dimensions of structural pressure, two ratios that capture what announced numbers conceal, and four years of post-ChatGPT data. The companion scorecard makes every score, signal and rule available for inspection and challenge.
The bubble debate has effectively exhausted itself. With Fink and Dimon publicly rejecting the framing this month, the question that animated AI economics commentary through 2024 and 2025 is no longer the live one. The live question is which transition unfolds from here, and on what timeline. That is the question this framework was built to answer.
Two observations close the paper. The first is that AI compute economics is unlikely to follow the dotcom pattern. The dotcom analogy fails on three counts: hyperscaler valuations are nowhere near Cisco’s peak, the buildout is funded primarily from operating cash flow rather than equity issuance, and AI demand has a working elasticity mechanism that fibre never had. EAR is not just a metric. It is the structural reason that catastrophic correction is harder for AI than it was for telecommunications.
The second is that the real risk in the system is transition risk. The question is whether the industry walks from today’s Catch-up Buildout into Balanced Expansion, or from today’s Vapor Capex condition into delayed overshoot. Both paths exist. Which one materialises depends on whether bottlenecks ease in step with demand or ahead of it, and on whether EAR stays above one or breaks below it.
Watch the indicators. The system will tell you which path is unfolding well before anyone else does.
The companion scorecard, which includes signal-level provenance, dimension scoring, condition rules, scenario assumptions and figure data, is published alongside this paper. All formulas, scores and assumptions are editable, so that readers can apply their own judgment and reach their own conclusions. The framework is intended to be argued with.
This essay was first published on the Brain AI Insights page on 1 May 2026.
Intelligence is becoming a general-purpose economic input rather than a feature inside software, and its addressable market is expanding rather than fixed.
Fifteen months ago, Anthropic was a $1 billion revenue business. Today it is a $30 billion one. That is not a typo.
In the same period, ChatGPT grew from 400 million to 900 million weekly active users. OpenAI crossed $25 billion in annualised revenue. Enterprise customers spending over $1 million annually with Anthropic doubled from 500 to 1,000 in under two months.
These are not the signals of a speculative bubble. They are the signals of a market whose total addressable size is being systematically underestimated.
Figure 1. The three forces expanding the market for intelligence. Falling unit cost, rising consumption per task, and the shift from software budgets to services budgets.
For years we sized technology markets in familiar buckets: software TAM, cloud TAM, services TAM, advertising TAM. AI is breaking those categories apart.
Intelligence is no longer a feature inside software. It is becoming a programmable layer that sits across workflows, devices, interfaces, and increasingly autonomous systems. If intelligence becomes abundant, cheap, and deployable almost everywhere, the addressable market is no longer a narrow AI software category. It starts to resemble the market for better decisions, faster execution, lower coordination cost, richer personalisation, and entirely new classes of digital labour.
Not because the market is literally infinite. Energy, compute, budgets, regulation, and organisational readiness all still matter. But the market for intelligence appears to be economically open-ended in a way traditional software categories are not. As the unit cost of intelligence falls, the number of viable use cases expands. And as model capability rises, each workflow can consume more intelligence, not less.
That is the setup for a Jevons paradox market.
Jevons paradox: why falling costs expand the market
Jevons paradox tells us that when efficiency improves, total consumption can rise rather than fall. We saw it with coal. We saw it with computing. We saw it with bandwidth and storage. We are beginning to see it with intelligence.
Gartner forecasts that by 2030, performing inference on a one-trillion-parameter model will cost providers more than 90% less than in 2025, and that these models will be up to 100 times more cost-efficient than similarly sized early models from 2022. Those gains come from better semiconductors, model design, higher utilisation, inference-specific silicon, and increased use of edge devices.
Meanwhile, academic analysis of token pricing suggests that economy-tier inference prices have already fallen roughly 600-fold since 2020, with some models around $0.09 per million tokens by early 2026. At that price, processing a 100-page document costs approximately $0.003. Intelligence becomes essentially free for simple tasks like email sorting, basic customer support, or grammar checking, which is why we are seeing AI integrated into almost every app and device.
Figure 2. Inference cost decline. Economy-tier token prices have fallen roughly 600-fold since 2020, with Gartner projecting a further 90% reduction by 2030.
The real unlock: more intelligence consumed per task
Gartner notes that agentic models can require 5 to 30 times more tokens per task than a standard chatbot. A chatbot produces an answer. An agent reasons across steps, calls tools, retrieves context, evaluates options, retries, plans, and executes actions. Each useful unit of work consumes materially more intelligence.
So the economics move in two directions at once. The cost per token is falling sharply, and the tokens consumed per useful task can rise dramatically as systems become more agentic.
The market does not have to choose between lower prices and higher demand. It can have both. Intelligence gets cheaper per unit, but richer workflows consume more of it. The result is not a collapse in value. It is a broadening and deepening of demand.
Figure 3. Tokens consumed per task. Agentic workflows consume 5 to 30 times more tokens than a single-turn chatbot exchange.
This is why the argument that token optimisation kills the market misses the point. Routing, caching, smaller specialist models, better context handling, and hybrid model stacks will all push effective unit costs down further. But that does not shrink the market. It opens the door to always-on intelligence in thousands of use cases that were previously too expensive to justify.
Revenue is now scaling exponentially
Anthropic: enterprise demand is real and accelerating. Anthropic’s annualised revenue run-rate trajectory in 2026 has been remarkable: approximately $9 billion at the end of 2025, $14 billion in February 2026, $19 billion in March, and more than $30 billion in April. That is a more than threefold increase in roughly four months.
The number of enterprise customers spending over $1 million annually doubled from 500 to 1,000 in less than two months. Claude Code alone was generating over $2.5 billion in annualised run-rate revenue by February. Anthropic also announced a compute agreement with Google and Broadcom for approximately 3.5 gigawatts of next-generation TPU capacity starting in 2027.
OpenAI: consumer intelligence as a mass utility. If Anthropic is proving enterprise willingness to pay, OpenAI is proving intelligence can behave like a mass consumer utility. ChatGPT reached 900 million weekly active users as of February 2026, up from 400 million a year earlier. It now has over 50 million paying consumer subscribers and more than 9 million paying business users. Annualised revenue exceeds $25 billion, with OpenAI reporting $2 billion in monthly revenue. 92% of Fortune 500 companies use the platform.
Figure 4. Revenue trajectory. Anthropic from roughly $9 billion annualised at the end of 2025 to more than $30 billion by April 2026, alongside OpenAI above $25 billion.
AI is no longer just one thing. It is simultaneously a consumer utility used weekly by nearly a billion people and an enterprise production layer monetised across APIs, coding, workflow augmentation, and agentic execution. That is not how narrow software categories behave. It is how foundational infrastructure behaves.
Intelligence does not just replace software, it replaces services
Here is where the argument gets larger. Sequoia Capital’s Julien Bek framed it sharply in March 2026: for every dollar spent on software, six are spent on services. If AI is only competing for the software budget, we are measuring the wrong market.
The key insight is the distinction between selling the tool and selling the work. A copilot sells the tool, making a professional more productive. An autopilot sells the work, and the customer buys the outcome directly. When AI becomes capable enough, the addressable market shifts from the tool budget to the labour budget. And the labour budget is multiples larger.
Insurance brokerage alone is $140 to $200 billion. IT managed services exceed $100 billion. Recruitment and staffing exceeds $200 billion. Management consulting is $300 to $400 billion. These are not software markets. They are services markets that intelligence is beginning to enter.
Figure 5. Services markets that intelligence is entering. Management consulting, recruitment and staffing, insurance brokerage and IT managed services, sized against the software budgets AI is usually measured against.
Sequoia’s framework maps every services vertical on an intelligence-to-judgement spectrum. The higher the intelligence ratio in any field, the sooner AI autopilots will win. Software engineering got there first, and more tasks are now started by agents than by humans in tools like Cursor. But it is coming to accounting, legal, healthcare billing, insurance, tax advisory, and procurement.
The next $1 trillion company will be a software company masquerading as a services firm.
Julien Bek, Sequoia Capital
This reframes the entire conversation. AI is not just a better tool for existing software workflows. It is a substitute for professional services labour. And the professional services market is measured in trillions, not billions.
Frontier plus open source: the market expands in both directions
The strongest future state is not frontier or open source. It is frontier plus open source. Frontier models anchor the highest-value reasoning, multimodal, and agentic workloads. Open and lower-cost models expand the market downward by making intelligence cheap, customisable, and deployable inside more products and workflows.
Falling economy-tier prices do not cannibalise the category. They widen it. They allow more applications to become viable while premium models capture the most demanding work. That layered structure is exactly what you would expect in a market that is still expanding.
Enterprise adoption is still remarkably low
Despite the visibility of AI, enterprise penetration remains early. Eurostat reports 20% of EU enterprises with ten or more employees used AI technologies in 2025, with a steep size gap: 55% for large enterprises against just 17% for small ones. OECD data shows 20.2% of firms using AI in 2025, up from 8.7% in 2023, a 132% increase, but still early.
Deloitte’s 2026 State of AI report found that worker access to AI rose 50% in 2025, but only 34% of organisations are truly reimagining their business with AI. McKinsey found only one-third of respondents were scaling AI across their organisations. The bottleneck is no longer whether the technology works. It is increasingly whether the organisation can deploy it safely, responsibly, and at scale.
Figure 6. Enterprise penetration. Roughly one in five firms across the EU and OECD were using AI in 2025, with a wide gap between large and small enterprises.
The use case explosion is just beginning
We have seen an explosion in chatbots, coding assistants, writing help, and copilots. But the larger categories are still nascent: agentic workflows, AI-native business processes, machine-to-machine coordination, scientific AI, industrial AI and robotics, edge AI, domain-specific agents, and personal AI. Models are improving rapidly, costs are falling, and each improvement unlocks new categories.
The constraint is not demand, it is energy and compute
The International Energy Agency makes it plain: affordable, reliable, and sustainable electricity supply will be a crucial determinant of AI development. Anthropic has secured approximately 3.5 gigawatts of future TPU capacity. OpenAI’s Stargate initiative has discussed a 10-gigawatt buildout. Hyperscalers collectively are planning hundreds of billions in AI infrastructure spending.
A saturated market asks where the demand is. This market increasingly asks whether capacity can be built fast enough. That is a profoundly different signal.
Does this settle the bubble argument?
This evidence does not prove that every part of the AI stack is fairly priced. It does not mean every infrastructure dollar will earn an adequate return. History suggests platform shifts come with pockets of excess.
But it does weaken the simplistic version of the bubble thesis considerably. That argument rests on the claim that AI demand is mostly speculative. The evidence is increasingly inconsistent with that claim. Consumer usage is massive, at 900 million weekly active users on one platform alone. Enterprise monetisation is real, at a $30 billion run-rate for Anthropic and $25 billion for OpenAI, with more than a thousand enterprises paying over $1 million a year. Revenue growth is exponential. Agentic workflows consume 5 to 30 times more tokens per task. Unit costs are collapsing. Penetration remains at roughly 20% of enterprises across the EU and OECD. And the services market is opening up.
That is not the profile of a category that has exhausted its market. It is the profile of a category that may still be very early in converting capability into deployment, and deployment into economic value.
The real conclusion
The most useful way to think about AI now is not as a single product market but as the emergence of programmable intelligence as infrastructure.
As intelligence gets cheaper, more capable, and easier to embed, more of the economy becomes addressable. As systems become agentic, each workflow consumes more intelligence, not less. As governance improves, more enterprises move from experimentation to scale. As AI shifts from copilot to autopilot, it captures not just the software budget but the vastly larger services budget. And because adoption remains relatively early, the distance between today’s usage and tomorrow’s usage may still be very large.
The addressable market for intelligence is not literally infinite. But it may be far more expansive than the market still assumes. Because intelligence is no longer just a feature inside software. It is becoming a general-purpose economic input. And when a scarce input becomes abundant, programmable, and cheap enough to use everywhere, history suggests something important: demand does not plateau. It compounds.
Sources and references
Gartner, inference cost projections for 2030, March 2026.